Featureless models
The two models you have built read records as your application stores them. Nothing aggregated the transactions into columns, encoded the merchants as integers, scaled the amounts, or padded the histories to one width. This page names the automated systems behind that, so you can judge what relflow replaces and what remains your work.
Two ways to model a payment
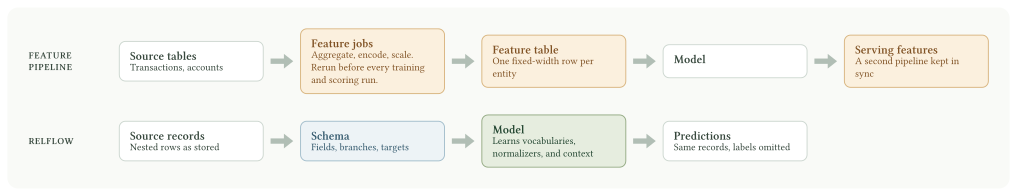
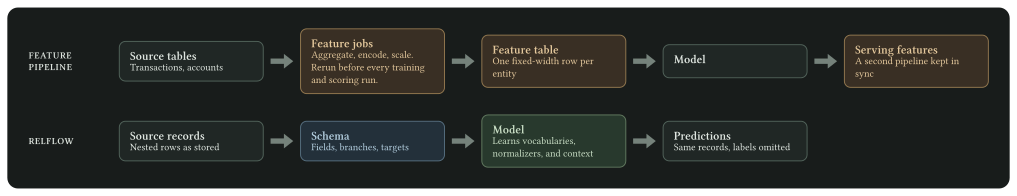
A conventional pipeline turns records into a fixed-width feature table before the model sees them. Someone writes the jobs that compute counts, totals, and recency windows, fits label encoders and scalers on training data, and stores their state. The same jobs run again before every scoring run, and a serving path has to reproduce them exactly. Each new idea about the data is a new column, and the model only ever sees the columns someone thought to build.
relflow reads the records themselves. The schema says what each value means and how the records nest; the model learns everything else from training batches.
What the schema automates
| Feature pipeline step | What relflow does instead | Where to read more |
|---|---|---|
| Encode labels as integers with an encoder fitted offline, and decide what to do with unseen labels | Category, Set, and Cluster learn labels from training batches. Storage grows as new labels arrive. An unknown label at prediction stays a valued input whose content is marked unavailable. |
Online vocabulary |
| Fit scalers on training data and store them beside the model | Number learns online normalization statistics and Quantile learns a distribution. Both are saved in the model artifact. |
Number, Quantile |
| Aggregate a history into counts, totals, and recency columns | A Branch keeps each event’s fields together. Attention within an event and across the sequence learns which combinations matter, and a learned summary reaches the parent. |
How fields interact, Branch summaries |
| Pad or truncate every history to one width | Branch widths follow each batch. A cap is optional, and predictions return variable lists. | Branch |
| Flatten nested records into one row per entity | Nested Arrow structs and lists are read directly from Parquet, including branches inside branches. | Data modules, Nested context and account outcomes |
| Separate label columns and check for leakage by hand | mask=True declares a target and keeps it out of the input. Prediction requests omit it. |
Masking and reconstruction |
| Maintain a second feature path for serving | One preprocessor attaches to training, batch prediction, and the HTTP deployment. The artifact carries the schema, vocabularies, and normalizers. | Preprocessing, Serving |
| Train one model per outcome | Targets at different levels of one observation share context and train together. | Nested context and account outcomes |
| Use labeled rows only | Reconstruction objectives learn from unlabeled histories, and learned context can be exported for other predictors. | Pretraining and fine-tuning, Reusable representations |
Each of these is learned state inside the model rather than a job outside it. After training, you can inspect what was learned:
import relflow as rf

merchants = rf.Category.vocabulary(model, rf.Address("trxns", "merchant"))
amounts = rf.Number.normalization(model, rf.Address("trxns", "amount"))
merchants is the tuple of labels the field learned, and amounts is the snapshot of mean, variance, and count used to standardize the amount. Saving the model preserves both.
What stays yours
relflow does not assemble observations. Your application still joins the records that belong to one decision, orders them, cuts them at the decision time, and attaches labels after the outcome window closes. Prepare observations defines those rules once.
Exact business arithmetic also stays outside the model. A learned summary of a history is not a ledger, and calendar parts are not elapsed time. When a rule needs an exact value, compute it in a preprocessor and let the model read it as another field. The proofs record what the architecture can learn and where it loses information.
How to judge the value
The honest comparison is against your current aggregate-feature model on the same held-out decision windows. Keep the eligible payments, available evidence, and outcome definitions identical, then add one thing at a time: the history, then more fields, then shared targets. Evaluation lays out that sequence. Preserving individual events costs preparation, retained records, and model computation; choose it when the comparison justifies it.
Next, prepare observations: the one data contract every later page relies on.