"""P065: report stable reconstruction quality alongside pretraining coverage."""

from collections.abc import Iterator
from functools import partial

import lightning.pytorch as lit
import numpy as np
from reporting import report

import relflow as rf

PROOF_ID = "P065"
BUDGET = 800
LABELS = tuple(f"class-{index}" for index in range(8))


def records(*, rows: int, seed: int) -> Iterator[dict]:
    rng = np.random.default_rng(seed)
    for index, label in enumerate(rng.integers(0, len(LABELS), rows)):
        yield {"x": f"cue-{label}", "code": LABELS[label], "hide": index % 2 == 0}


def build() -> rf.Model:
    model = rf.Model(
        d_model=32,
        n_layers=1,
        n_heads=4,
        batch_size=64,
        dropout=0.0,
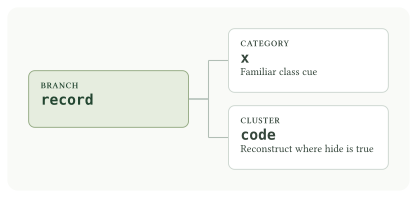
        x=rf.Category(p_unavailable=0.0),
        code=rf.Cluster(n_clusters=8, p_unavailable=1.0, mask=rf.Mask(query="hide", reconstruct=True)),
    )
    model.optimizer = rf.adamw(learning_rate=0.002)
    return model


def evaluate(trainer: lit.Trainer, model: rf.Model, rows: list[dict]) -> dict[str, float]:
    data = rf.SyntheticDataModule(model=model, validate=lambda: iter(rows), seed=0)
    result = trainer.validate(model, datamodule=data, verbose=False)[0]
    prefix = ".code/validate."
    return {name.removeprefix(prefix): float(value) for name, value in result.items() if name.startswith(prefix)}


def run(seed: int, steps: int | None, accelerator: str) -> tuple[dict, dict]:
    lit.seed_everything(seed, workers=True)
    model = build()
    data = rf.SyntheticDataModule(
        model=model,
        train=partial(records, rows=8192, seed=seed + 1),
        validate=partial(records, rows=1024, seed=seed + 2),
        seed=seed,
    )
    trainer = lit.Trainer(
        accelerator=accelerator,
        devices=1,
        max_epochs=-1,
        max_steps=BUDGET if steps is None else min(steps, BUDGET),
        logger=False,
        enable_checkpointing=False,
        enable_progress_bar=False,
        enable_model_summary=False,
        deterministic=True,
        num_sanity_val_steps=0,
    )
    trainer.fit(model, datamodule=data)
    original = list(records(rows=2048, seed=seed + 3))
    vocabulary = rf.Cluster.vocabulary(model, "/code")
    counts = tuple(model.nodes["/code"].embedder.counters["content"].counts.tolist())
    metrics, checks = {}, {}
    for keep in (1024, 512, 102, 0):
        selected = 0
        rows = []
        for row in original:
            unavailable = row["hide"] and selected >= keep
            rows.append({**row, "code": f"novel-{row['code']}" if unavailable else row["code"]})
            selected += int(row["hide"])
        measured = evaluate(trainer, model, rows)
        # Keep undefined quantities explicit without nonstandard JSON NaNs.
        metrics[f"known_{keep}"] = {name: value if np.isfinite(value) else None for name, value in measured.items()}
        checks[f"{keep}: exact known and unavailable target counts"] = (
            measured.get("targets.known") == keep and measured.get("targets.unavailable") == 1024 - keep
        )
        checks[f"{keep}: coverage matches selected targets"] = (
            abs(measured.get("coverage.content", -1) - keep / 1024) < 1e-7
        )
        if keep:
            checks[f"{keep}: known accuracy exceeds 0.95"] = measured.get("accuracy.content", -1) > 0.95
            checks[f"{keep}: all-target accuracy includes unavailable errors"] = (
                abs(measured.get("accuracy.all", -1) - measured.get("accuracy.content", 0) * keep / 1024) < 1e-7
            )
        else:
            checks["All-OOV conditional scores are undefined"] = all(
                name in measured and np.isnan(measured[name])
                for name in ("accuracy.content", "nll.content", "loss.content")
            )
            checks["All-OOV all-target accuracy is zero"] = measured.get("accuracy.all") == 0
        if keep == 102:
            rng = np.random.default_rng(seed + 4)
            permuted = [rows[index] for index in rng.permutation(len(rows))]
            regrouped = evaluate(trainer, model, permuted)
            names = (
                "targets.known",
                "targets.unavailable",
                "coverage.content",
                "accuracy.content",
                "accuracy.all",
                "nll.content",
                "loss.content",
            )
            drift = (
                max(abs(measured[name] - regrouped[name]) for name in names)
                if all(name in measured and name in regrouped for name in names)
                else None
            )
            metrics["batch_partition_drift"] = drift
            metrics["reported_content_loss_drift"] = abs(measured["loss.content"] - regrouped["loss.content"])
            checks["Rebatching preserves counts and scores"] = drift is not None and drift < 1e-5
    checks["Validation leaves mapping and exposures frozen"] = (
        rf.Cluster.vocabulary(model, "/code") == vocabulary
        and tuple(model.nodes["/code"].embedder.counters["content"].counts.tolist()) == counts
    )
    return metrics, checks


if __name__ == "__main__":
    report(PROOF_ID, run, seed=7651)