Query Paths
Use query= when a model node reads a differently named or nested source. Every path starts from the value selected by its parent node.
One source record:
request_id: order-42
payload:
  items:
    - product:
        sku: coat-17
      qty: 1
    - product:
        sku: scarf-03
      qty: 2
  outcome: false
import relflow as rf
model = rf.Model(
name="order",
query="payload",
d_model=64,
n_layers=2,
n_heads=4,
items=rf.Branch(
query="items[-32:]",
length=32,
sku=rf.Category(query="product.sku", size=4096),
quantity=rf.Number(query="qty"),
),
returned=rf.Boolean(query="outcome", mask=True),
)The root selects payload. The branch selects its last 32 items, then each child reads relative to an item. Children do not repeat the parent’s path.
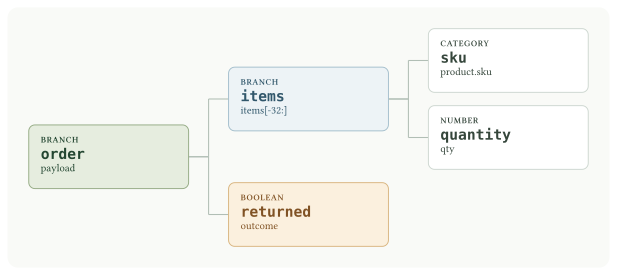
Without a query, the root uses the source row and a child selects its own name. A child branch must select a list of structs. Branch queries select source positions; length sets the model’s capacity and padding.
Path syntax
| Path | Selection |
|---|---|
customer.name |
A nested struct member |
["gross amount"] |
A member whose name needs quoting |
items[*].sku |
A leaf value across one list axis |
legs[0].origin |
One position; negative indices count from the end |
events[-10:] |
A slice of each list |
attributes["country"] |
One literal Arrow map key |
[*] retains a list axis; it does not flatten it. Use it when a leaf path crosses an unmodeled list. Children of a modeled branch already operate on each branch element.
Slices use half-open, clamped bounds; steps such as [::2] are unsupported. Map keys may be strings, integers, or booleans that match the Arrow key type exactly. Duplicate matches are errors. Paths have no $ source-root prefix.
Structural absence
| Source condition | Result |
|---|---|
| Present, non-null value | valued |
| Present field with a null value | null |
| Null ancestor, out-of-range list index, or absent map key | padded |
| Required field absent from the Arrow schema | Binding error |
An omitted key in a Python record and an explicit null can become the same Arrow null slot. Represent a distinction explicitly if your application needs it.
Transform values before querying
Queries navigate structure. They do not filter, join, sort, compute expressions, or stack fields. A Polars preprocessor can filter whole event structs so sibling fields stay aligned:
import polars as pl

@rf.preprocess
def logins(frame: pl.DataFrame) -> pl.DataFrame:
    return frame.with_columns(
        events=pl.col("events").list.eval(
            pl.element().filter(
                pl.element().struct.field("kind").eq("login").fill_null(False)
            )
        )
    )
For data-dependent masking, derive a non-null Boolean column in a preprocessor and select it with rf.Mask(query="hide_amount", ...). The selector is relative to the mask owner’s records and must contain one Boolean per owner. See Dynamic Masking.
Targets at prediction time
A directly bound mask=True target may be omitted from prediction input. Its containing repeated branches must remain: their lists define output positions. Training, validation, and testing still need target values.
An explicitly queried target, such as returned above, must retain its queried source structure and field schema at prediction time. Prefer a directly bound target when prediction requests should omit the label entirely.
When a query fails, inspect the processed Arrow schema, then read the path from its parent’s selected value. Errors identify the query segment and model address. See Preprocessing for preparing nested records and shared roles.