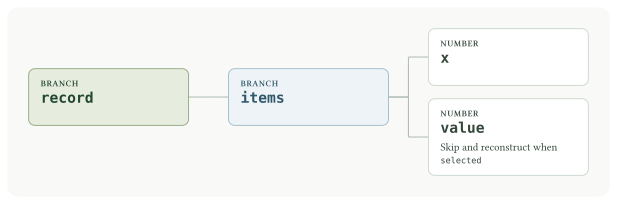
"""P052: query-selected reconstruction over variable-length repeated records."""

from collections.abc import Iterator
from functools import partial

import lightning.pytorch as lit
import numpy as np
import pyarrow as pa
from reporting import report

import relflow as rf

PROOF_ID = "P052"
LENGTH = 4
BUDGET = 400


def records(*, rows: int, seed: int) -> Iterator[dict]:
    rng = np.random.default_rng(seed)
    for _ in range(rows):
        length = int(rng.integers(1, LENGTH + 1))
        values = rng.uniform(-1.0, 1.0, length)
        selected = rng.random(length) < 0.5
        selected[int(rng.integers(length))] = True
        yield {
            "items": [
                {"x": float(value), "value": float(2 * value + 0.3), "selected": bool(chosen)}
                for value, chosen in zip(values, selected, strict=True)
            ]
        }


def build() -> rf.Model:
    return rf.Model.xs(
        batch_size=64,
        items=rf.Branch(
            length=LENGTH,
            reduction=None,
            x=rf.Number,
            value=rf.Number(objective="mse", mask=rf.Mask(query="selected", skip=True, reconstruct=True)),
        ),
    )


def prediction(model: rf.Model, rows: list[dict]) -> tuple[np.ndarray, np.ndarray]:
    output = model.predict(pa.Table.from_pylist(rows))["predictions"].to_pylist()
    # Evaluation compares real coordinates against fixed-width selector matrices.
    # Public output has no cap padding; absent coordinates receive no score.
    content = np.zeros((len(rows), LENGTH), dtype=np.float64)
    inferred = np.zeros((len(rows), LENGTH), dtype=bool)
    for index, row in enumerate(output):
        values = [item["value"] for item in row["items"]]
        content[index, : len(values)] = [value["content"] for value in values]
        inferred[index, : len(values)] = [value["inferred"] for value in values]
    return content, inferred


def run(seed: int, steps: int | None, accelerator: str) -> tuple[dict, dict]:
    lit.seed_everything(seed, workers=True)
    model = build()
    model.optimizer = rf.adamw(learning_rate=0.002)
    data = rf.SyntheticDataModule(
        model=model,
        train=partial(records, rows=2048, seed=seed + 1),
        validate=partial(records, rows=256, seed=seed + 2),
        seed=seed,
    )
    trainer = lit.Trainer(
        accelerator=accelerator,
        devices=1,
        max_epochs=-1,
        max_steps=BUDGET if steps is None else min(steps, BUDGET),
        deterministic=True,
        logger=False,
        enable_checkpointing=False,
        enable_progress_bar=False,
        enable_model_summary=False,
        num_sanity_val_steps=0,
    )
    trainer.fit(model, datamodule=data)
    model.eval()
    train = list(records(rows=2048, seed=seed + 1))
    test = list(records(rows=1024, seed=seed + 3))
    expected = np.asarray(
        [[item["selected"] for item in row["items"]] + [False] * (LENGTH - len(row["items"])) for row in test]
    )
    actual = np.asarray([item["value"] for row in test for item in row["items"] if item["selected"]])
    mean = float(np.mean([item["value"] for row in train for item in row["items"] if item["selected"]]))
    baseline = float(np.sqrt(np.mean((actual - mean) ** 2)))
    content, inferred = prediction(model, test)
    rng = np.random.default_rng(seed + 4)
    corrupted = [{"items": [{**item, "x": float(rng.uniform(-1, 1))} for item in row["items"]]} for row in test]
    poisoned = [
        {"items": [{**item, "value": 1000.0 if item["selected"] else item["value"]} for item in row["items"]]}
        for row in test
    ]
    broken, _ = prediction(model, corrupted)
    replaced, _ = prediction(model, poisoned)
    # Audit labels on an independent model, leaving fitted normalizers frozen.
    field = build().encode(pa.Table.from_pylist(test), strata="train")["/items/value"]
    measured = float(np.sqrt(np.mean((content[expected] - actual) ** 2)))
    metrics = {
        "steps": trainer.global_step,
        "selected_coordinates": int(expected.sum()),
        "rmse": measured,
        "baseline_rmse": baseline,
        "nrmse": measured / baseline,
        "corrupted_context_nrmse": float(np.sqrt(np.mean((broken[expected] - actual) ** 2))) / baseline,
        "hidden_value_drift": float(np.max(np.abs(content[expected] - replaced[expected]))),
    }
    return metrics, {
        "Selected held-out nRMSE below 0.25": metrics["nrmse"] < 0.25,
        "Corrupted context nRMSE above 0.85": metrics["corrupted_context_nrmse"] > 0.85,
        "Hidden values cannot affect predictions": metrics["hidden_value_drift"] < 1e-5,
        "Prediction flags match selectors including padding": bool(np.array_equal(inferred, expected)),
        "Training objectives match selectors including padding": bool(
            np.array_equal(field.trainable.cpu().numpy().reshape(expected.shape), expected)
        ),
        "Selected coordinates are absent from encoder input": not bool(
            field.present.cpu().numpy().reshape(expected.shape)[expected].any()
        ),
    }


if __name__ == "__main__":
    report(PROOF_ID, run, seed=5201)