Selecting and summing supplied contributions

Grouped weighted aggregation
Test group selection and summation without also requiring the model to learn multiplication.

Seed 3600 on gpu: 6 of 6 behavioral checks met. See the measurements below. The experiment code has changed since this run; these measurements describe its earlier version.

Insights

The model can select and sum a requested group’s supplied contributions. Each bag is reused with different requests, and rotating item group labels breaks accuracy against the original answer. That makes the association between groups and contributions relevant, rather than allowing one answer for the whole bag.

The products are already present, so this case tests selection and reduction without establishing learned multiplication. Compare it with the raw-pair proof when diagnosing a difficult schema. The two routes expose different numbers of input fields, so their scores are not a matched comparison of model capacity. Missing groups and new category labels also remain outside this case.

Setup

Code
"""Supplied products isolate category selection and fixed-width summation.

Learn filtering and reduction after item-local products are supplied.

Run: uv run python proofs/run.py P011"""

from __future__ import annotations

from collections.abc import Iterator
from copy import deepcopy

import lightning.pytorch as lit
import numpy as np
import torch
from reporting import report

import relflow as rf

PROOF_ID = "P011"
GROUPS = ("A", "B", "C")
ITEMS_PER_GROUP = 2
ITEMS = len(GROUPS) * ITEMS_PER_GROUP

Examples

Targets use mask=True; the labels below are supervision hidden from the encoder.

Select supplied A contributions

selected_group: A
items:
  - {group: B, contribution: 0.4}
  - {group: A, contribution: 0.6}
  - {group: C, contribution: -0.2}
  - {group: A, contribution: -0.1}
  - {group: B, contribution: 0.3}
  - {group: C, contribution: 0.8}
answer: 0.5

The A contributions sum to 0.5; multiplication has already happened upstream.

Change only the request

selected_group: B
items:
  - {group: B, contribution: 0.4}
  - {group: A, contribution: 0.6}
  - {group: C, contribution: -0.2}
  - {group: A, contribution: -0.1}
  - {group: B, contribution: 0.3}
  - {group: C, contribution: 0.8}
answer: 0.7

Selecting B from exactly the same items changes the answer to 0.7.

Rotate group labels

selected_group: A
items:
  - {group: C, contribution: 0.4}
  - {group: B, contribution: 0.6}
  - {group: A, contribution: -0.2}
  - {group: B, contribution: -0.1}
  - {group: C, contribution: 0.3}
  - {group: A, contribution: 0.8}
answer: 0.5  # Retained original label

Rotating A → B → C → A makes the visible A items sum to 0.6. The negative control retains the original 0.5 target to check whether the model follows the changed group association.

Synthetic data and controls

Code
def records(*, bags: int, seed: int) -> Iterator[dict]:
    """Draw interleaved groups and emit one request for every selected group."""
    rng = np.random.default_rng(seed)
    for bag in range(bags):
        items: list[dict[str, object]] = []
        answers: dict[str, float] = {}
        for group in GROUPS:
            values = rng.uniform(-1.0, 1.0, size=ITEMS_PER_GROUP)
            weights = rng.uniform(0.2, 1.8, size=ITEMS_PER_GROUP)
            contributions = values * weights
            answers[group] = float(contributions.sum())
            for value, weight, contribution in zip(values, weights, contributions, strict=True):
                item: dict[str, object] = {"group": group}
                item["contribution"] = float(contribution)
                items.append(item)
        interleaved = [items[index] for index in rng.permutation(len(items))]
        for selected_group in GROUPS:
            yield {
                "bag": bag,
                "selected_group": selected_group,
                "items": interleaved,
                "answer": answers[selected_group],
            }


def rotate_group_labels(observations: list[dict]) -> list[dict]:
    """Break group/item association while preserving all group marginals."""
    successor = {group: GROUPS[(index + 1) % len(GROUPS)] for index, group in enumerate(GROUPS)}
    rows = deepcopy(observations)
    for row in rows:
        row["items"] = [{**item, "group": successor[item["group"]]} for item in row["items"]]
    return rows


def permute_items(observations: list[dict], *, seed: int) -> list[dict]:
    """Jointly permute complete items while retaining targets."""
    rng = np.random.default_rng(seed)
    rows = deepcopy(observations)
    cached: dict[int, list[dict[str, object]]] = {}
    for row in rows:
        bag = int(row["bag"])
        if bag not in cached:
            items = row["items"]
            cached[bag] = [items[index] for index in rng.permutation(len(items))]
        row["items"] = cached[bag]
    return rows


def prediction(model: rf.Model, observations: list[dict]) -> np.ndarray:
    inputs = [{"selected_group": row["selected_group"], "items": row["items"]} for row in observations]
    output = model.predict(inputs)["predictions"].to_pylist()
    return np.asarray([row["request/answer"]["content"] for row in output], dtype=np.float64)


def rmse(actual: np.ndarray, predicted: np.ndarray | float) -> float:
    return float(np.sqrt(np.mean(np.square(actual - predicted))))


def score(*, train: list[dict], test: list[dict], predicted: np.ndarray) -> dict[str, float]:
    """Compare held-out RMSE with the constant training-target mean."""
    actual = np.asarray([row["answer"] for row in test], dtype=np.float64)
    baseline_rmse = rmse(actual, float(np.asarray([row["answer"] for row in train], dtype=np.float64).mean()))
    measured = rmse(actual, predicted)
    return {"rmse": measured, "baseline_rmse": baseline_rmse, "nrmse": measured / baseline_rmse}

Model tree

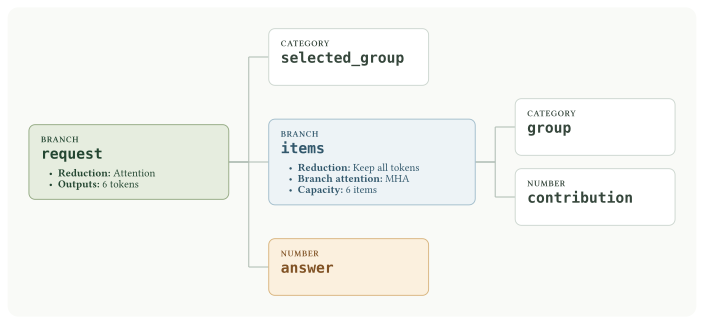
Request contains repeated items with group, contribution inputs, visible selected group, and hidden answer targets. Root reduction: Attention, 6 output tokens. Item reduction: Keep all tokens; capacity 6; branch attention MHA.

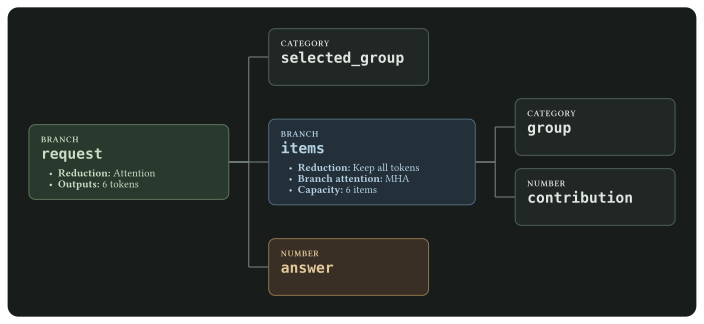
Request contains repeated items with group, contribution inputs, visible selected group, and hidden answer targets. Root reduction: Attention, 6 output tokens. Item reduction: Keep all tokens; capacity 6; branch attention MHA.

Figure 1: Group and contribution tokens are preserved; root Attention produces six outputs conditioned by the visible group request.

How it works

Every item receives a precomputed value–weight product. Its group stays beside that contribution in the repeated branch. reduction=None preserves these coordinates, and root rf.Attention combines them with a visible group request. Every six-item bag appears once for each of A, B, and C.

Rotating labels A → B → C → A changes which contributions answer the request while retaining all label counts and numerical values. The control keeps the original answer, so a group-sensitive model should score worse. Permuting complete items should leave predictions stable. The raw-pair proof adds the multiplication requirement that this diagnostic deliberately supplies.

Training and evaluation

Code
def run(seed: int, steps: int | None, accelerator: str) -> tuple[dict, dict]:
    lit.seed_everything(seed, workers=True)
    # Split seeds are independent; rerunning a generator reproduces the same records.
    train = list(records(bags=384, seed=seed + 1))
    test = list(records(bags=192, seed=seed + 3))
    model = rf.Model(
        name="request",
        d_model=48,
        n_layers=2,
        n_heads=4,
        reduction=rf.Attention(n_outputs=ITEMS, n_layers=2),
        batch_size=96,
        optimizer=lambda module: torch.optim.Adam(module.parameters(), lr=0.001),
        items=rf.Branch(
            length=ITEMS,
            n_layers=2,
            reduction=None,
            group=rf.Category(size=len(GROUPS), p_unavailable=0.0),
            contribution=rf.Number,
        ),
        selected_group=rf.Category(size=len(GROUPS), p_unavailable=0.0),
        answer=rf.Number(mask=True, objective="mse"),
    )
    datamodule = rf.SyntheticDataModule(
        model=model,
        train=lambda: records(bags=384, seed=seed + 1),
        validate=lambda: records(bags=96, seed=seed + 2),
        seed=seed,
    )
    trainer = lit.Trainer(
        accelerator=accelerator,
        devices=1,
        max_epochs=-1,
        max_steps=800 if steps is None else min(steps, 800),
        logger=False,
        enable_progress_bar=False,
        enable_model_summary=False,
        enable_checkpointing=False,
        deterministic=True,
        num_sanity_val_steps=0,
    )
    trainer.fit(model, datamodule=datamodule)

    # Evaluate held-out answers and retain their original labels in corruption controls.
    intact_prediction = prediction(model, test)
    intact = score(train=train, test=test, predicted=intact_prediction)
    corrupted = score(train=train, test=test, predicted=prediction(model, rotate_group_labels(test)))
    permuted_prediction = prediction(model, permute_items(test, seed=seed + 4))
    target_scale = float(np.std(np.asarray([row["answer"] for row in test], dtype=np.float64)))
    permutation_drift = rmse(intact_prediction, permuted_prediction) / target_scale
    metrics = {
        "intact": intact,
        "corrupted": corrupted,
        "permutation_drift": permutation_drift,
        "steps": trainer.global_step,
    }
    checks = {
        "All measurements finite": bool(
            all((np.isfinite(value) for value in (intact["nrmse"], corrupted["nrmse"], permutation_drift)))
        ),
        "Intact calibration nRMSE below 1.60": bool(intact["nrmse"] < 1.6),
        "Corrupt calibration nRMSE below 1.80": bool(corrupted["nrmse"] < 1.8),
        "Grouped contribution nRMSE below 0.50": bool(intact["nrmse"] < 0.5),
        "Rotated labels raise nRMSE by at least 0.20": bool(corrupted["nrmse"] >= intact["nrmse"] + 0.2),
        "Permutation drift below 0.10 target SD": bool(permutation_drift < 0.1),
    }
    return metrics, checks
Evidence

Latest full run

Seed 3600, gpu, recorded 2026-09-15T02:20:46.436531+00:00. Outcome: met.

Source fingerprint: b8adda32c5f5c52e2ac75517b67ba47e34f325d46ad60ae14baef2822def6f30. Python 3.12.6; Torch 2.12.0.

Measurement Value
intact rmse: 0.0679258; baseline_rmse: 0.916478; nrmse: 0.0741162
corrupted rmse: 1.27737; baseline_rmse: 0.916478; nrmse: 1.39378
permutation_drift 0.0308237
steps 800
Behavioral checks
Behavioral check Outcome
All measurements finite Met
Intact calibration nRMSE below 1.60 Met
Corrupt calibration nRMSE below 1.80 Met
Grouped contribution nRMSE below 0.50 Met
Rotated labels raise nRMSE by at least 0.20 Met
Permutation drift below 0.10 target SD Met

Recorded results.

Remaining work

Repeat across seeds and vary group counts independently of bag size. Absent groups and held-out labels need separate checks. Passing this control supports selection and reduction, not learned multiplication.

The family’s promotion target is at least three core seeds and ten lightweight calibration seeds.

Reproduce

Run by stable ID from the repository root:

uv run python proofs/run.py P011

Or run the self-contained script directly:

PYTHONPATH=proofs uv run python proofs/aggregation/selected_group_supplied_contribution_sum.py

Add --accelerator gpu for CUDA or --seed 42 for another seeded experiment. --steps 2 checks execution with a short training budget; it is recorded as a smoke run.

Download the complete proof.

Code
if __name__ == "__main__":
    report(PROOF_ID, run, seed=3600)