Learn an arithmetic mean while preserving predictions when complete items are reordered or duplicated.
Seed 3600 on gpu: 3 of 3 behavioral checks met. See the measurements below. The experiment code has changed since this run; these measurements describe its earlier version.
Insights
With item attention disabled, Mean preserves the answer when a whole bag is repeated. It averages encoded Number tokens, so duplicating every item leaves the representation unchanged. The decoder must still learn how that representation corresponds to the arithmetic mean of the raw amounts.
That invariance is useful for an average and destructive for a total. The same duplicated bag has twice the sum, which cannot be recovered from an unchanged summary without additional information. This proof checks learned mean accuracy together with permutation and duplication stability. It does not imply that every architecture containing Mean discards count; earlier item interaction can change what reaches the reducer.
Setup
Code
"""Mean is invariant here with item attention disabled.Learn average and retain it exactly under two multiset interventions.Run: uv run python proofs/run.py P003"""from __future__ import annotationsfrom collections.abc import Iteratorfrom copy import deepcopyimport lightning.pytorch as litimport numpy as npimport torchfrom reporting import reportimport relflow as rfPROOF_ID ="P003"TRAIN_MAX =6CAPACITY =12
Examples
Targets use mask=True; the labels below are supervision hidden from the encoder.
Learn the raw average
items:-{amount:0.2}-{amount:0.8}mean_amount:0.5
The desired average is 0.5; Mean itself averages encoded tokens rather than raw amounts.
Change the content
items:-{amount:-0.2}-{amount:0.8}mean_amount:0.3
Changing one amount changes the desired mean to 0.3.
Duplicating the first bag keeps its average at 0.5. With item attention disabled, the encoded Mean summary and downstream prediction stay unchanged to the precision required by the proof.
Synthetic data and controls
Code
def random_records(*, rows: int, seed: int, minimum: int=1, maximum: int= TRAIN_MAX) -> Iterator[dict]:"""Draw variable-length numerical bags and their mean and sum."""ifnot1<= minimum <= maximum <= CAPACITY:raiseValueError(f"length range must satisfy 1 <= minimum <= maximum <= {CAPACITY}") rng = np.random.default_rng(seed)for _ inrange(rows): length =int(rng.integers(minimum, maximum +1)) values = rng.uniform(-1.0, 1.0, size=length) row: dict[str, object] = {"items": [{"amount": float(value)} for value in values],"mean_amount": float(values.mean()),"total": float(values.sum()), }yield rowdef duplicate(observations: list[dict]) ->list[dict]:"""Duplicate every complete bag and update its algebraic targets.""" rows = deepcopy(observations)ifany((len(row["items"]) *2> CAPACITY for row in rows)):raiseValueError(f"duplicated collection exceeds configured capacity {CAPACITY}")for row in rows: row["items"] = [*row["items"], *row["items"]] row["total"] *=2.0return rowsdef permute(observations: list[dict], *, seed: int) ->list[dict]:"""Jointly permute complete items without changing any target.""" rng = np.random.default_rng(seed) rows = deepcopy(observations)for row in rows: items = row["items"] row["items"] = [items[index] for index in rng.permutation(len(items))]return rowsdef prediction(model: rf.Model, observations: list[dict]) -> np.ndarray: inputs = [{"items": row["items"]} for row in observations] output = model.predict(inputs)["predictions"].to_pylist()return np.asarray([row["record/mean_amount"]["content"] for row in output], dtype=np.float64)def rmse(actual: np.ndarray, predicted: np.ndarray |float) ->float:returnfloat(np.sqrt(np.mean(np.square(actual - predicted))))def score(*, train: list[dict], test: list[dict], predicted: np.ndarray) ->dict[str, float]:"""Compare held-out RMSE with the constant training-target mean.""" actual = np.asarray([row["mean_amount"] for row in test], dtype=np.float64) baseline = rmse(actual, float(np.asarray([row["mean_amount"] for row in train], dtype=np.float64).mean())) measured = rmse(actual, predicted)return {"rmse": measured, "baseline_rmse": baseline, "nrmse": measured / baseline}
Model tree
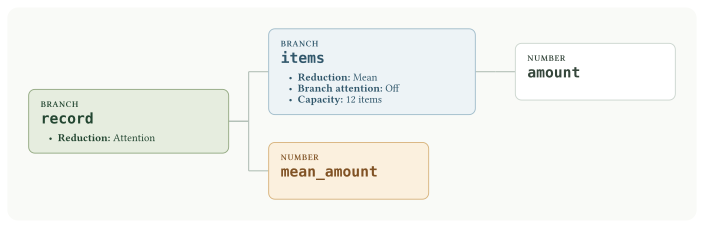
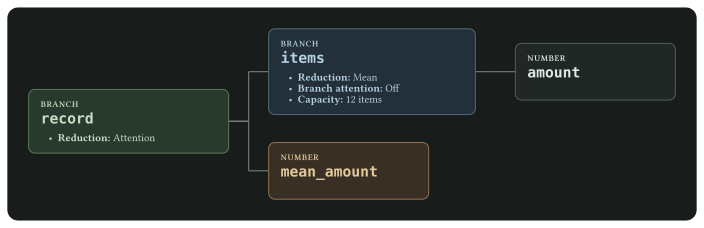
Figure 1: With item attention off, Mean preserves the encoded average under complete-bag duplication.
How it works
The item branch uses attention=None and rf.Mean(). It averages encoded Number tokens rather than directly averaging raw amounts. A learned downstream path must still map that representation to the arithmetic-mean target.
Without preceding item attention, permuting tokens or duplicating the complete bag leaves their encoded average unchanged. The test checks both invariances at numerical precision. This is correct for the mean target; a sum would change from 1.0 to 2.0 when the illustrated bag is duplicated and could not be recovered from the same summary without additional count information.
Repeat across seeds and test missing values, empty collections, and nested placement. The invariance applies to this no-item-attention path; it does not imply that every model using Mean is insensitive to multiplicity.
The family’s promotion target is at least three core seeds and ten lightweight calibration seeds.
Reproduce
Run by stable ID from the repository root:
uv run python proofs/run.py P003
Or run the self-contained script directly:
PYTHONPATH=proofs uv run python proofs/aggregation/mean_duplicate_invariance.py
Add --accelerator gpu for CUDA or --seed 42 for another seeded experiment. --steps 2 checks execution with a short training budget; it is recorded as a smoke run.